Latest
He Banned AI From His Writing Group. His Own Cover Got Called AI Slop.Who Writes the Fake Fan Mail Authors Get? Inside the Scam CompoundsSMS Appointment RemindersDarrell Stern: Stop Being Invisible, Become UnmissableJoe Rockey: Ghostwriting His BookFree BooksHow to Turn Your Expertise Into a Book People Want to Read | The Expert MethodWhat’s New at The Writing King: Week of October 25, 2026Challenger Remembrance Day: The Engineer Who Wouldn’t SignJoel Salomon: The Truth About MoneyReddit Is Putting Up a Login Wall. Wikipedia Won’t Be Far Behind.Victoria Chemko: The Body Is the First TechnologySir Patrick Stewart: A TributeA Year in the Bank: ADHD, Face Blindness and the Freedom to Walk Out | The Impossible Puzzles Show, Episode 326A Yale Economist Says We Won’t Be Missed. He Forgot the Bread Line.Walter Koenig: A TributeI Don’t Post Bad ARC Reviews. I Send the Author a Note.AI Has Paid Off Outside Tech. Apollo Is Reading the Wrong Scoreboard.The Little Red Book of Stuff That Works!Your Kids Are Your Own FaultGrow a PairYou’re Broke Because You Want to BeIt’s Called Work for a Reason!No Time for TactShut Up, Stop Whining, and Get a LifeWilliam Bessette: AI Enablement and Child Welfare TechnologyFree Book Planning ToolsWhat’s New at The Writing King: Week of October 18, 2026Ghostwriting by the Numbers: Timelines, Word Counts and the First CallPromising Young Woman (2020) ReviewBillions for AI, Pennies for the Plumbing: AI Companies Should Pay to Keep PHP AlivePHP2Shell: AI Found a 22-Year-Old Crack Under Your Website in Two DaysPetrov Day: The Officer Who Didn’t Believe the ComputerKindle Unlimited Is Now Kindle+. AI Audiobooks Just Joined the BuffetChina Is Using Bots to Fan the Data Center Backlash. The Backlash Is Still Real.The Society of Authors Signed an Ethical AI Charter, Then Ran From It in Eight DaysWhen to Quit Writing a Book: I’ve Abandoned Dozens, and I’d Do It AgainMo Gawdat Says the AI Dystopia Starts in 2027. Read the List, Skip the DatesGetty Images Filed for Bankruptcy. Can You Prove You Licensed Your Book’s Images?Fluff Words: Cut Them From Your Prose, Keep Them in Your DialogueWhere Can Writers Learn Storytelling From Movies? Richard Lowe Publishes 1,226 Film and TV Reviews With Writing Craft NotesWhere Are the Independent Bookstores and Public Libraries Worth Visiting in Tampa Bay? Author Richard Lowe Profiles 44 of ThemWhat Should You Know Before Hiring a Ghostwriter? The Writing King Publishes 57 New Answers, Including What to Do When It Goes WrongWhere Can You Hear Founders and Executives Tell Their Own Stories? Richard Lowe’s Leaders and Their Stories Publishes Every Unscripted Interview With a Full TranscriptAuthor Richard Lowe Publishes Eight Volumes of Enemies of You, a Researched Series on the Forces Working Against Ordinary AmericansThe Jackal (1997) ReviewThe Day of the Jackal (2024) ReviewYour First Novel Is an Apprentice Piece: What Beta Readers and Editors Can’t FixWhen the Cloud Gets Bombed: What the AWS Data Center Strikes Teach About BackupsHuman-Written Book Labels Are Gatekeeping With a Fee
The Writing King Your Ethical Ghostwriter. Your Story, Done Right.

The Day Every Safety Net Failed: Anatomy of a Cascading Disaster

TL;DR: In one morning we lost the power, the generator, the UPS coverage, the cache battery, the link to the disaster site, and the tape backup. Six independent safety nets, six failures. I ran disaster recovery for twenty years, and this was the day that taught me the discipline. The company came back because one consultant rebuilt a disk mapping table by hand, from memory, and afterward I tore the guts out of that computer room and rebuilt everything redundant. The deeper lesson: I had ordered full redundancy years earlier, and nobody told me one cabinet didn’t have it.

I was a hundred and thirteen miles from the office, driving north to a Renaissance fair with a camera on the seat beside me, when my consultant called. Three friends in full pirate costume were waiting for me at the fairgrounds. This was going to be a great day. It was the Kearney Park Renaissance Faire in Fresno.
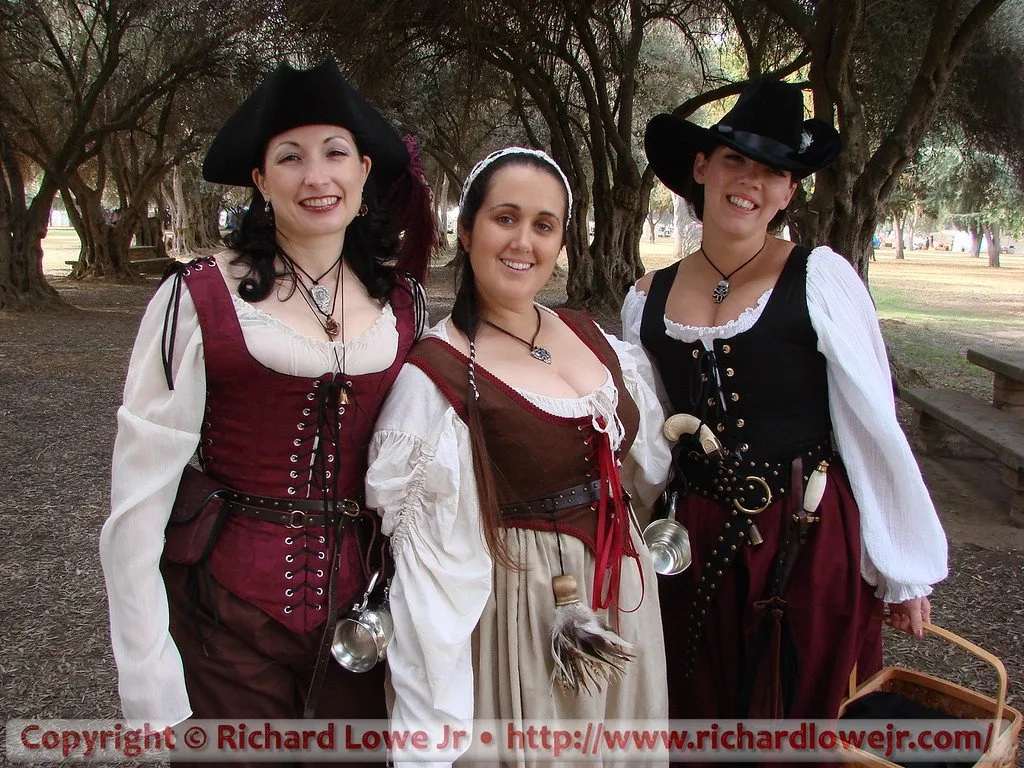
Three women in pirate costumes at the Kearney Park Renaissance Faire in Fresno, California

My three friends in pirate costume at the Kearney Park faire in Fresno, the day the computers went down. Copyright © Richard Lowe.

“Richard,” he said, “you do know about the crash.”

I didn’t know about the crash. What followed was a phone call I have retold for decades. Each exchange in it removed a safety net I believed we had. By the end there were none left.

How did each safety net fail in the cascade?

Six safety nets that failed in one morningA power outage near the data center removed one safety net after another: the generator, the UPS coverage, the cache battery, the link to the disaster recovery site, and the tape backup. The company came back only when a consultant rebuilt the disk mapping table by hand from memory.How the safety nets failed, in orderSix layers built so no single failure could hurt us1Power,thengeneratorArea powerfailed2UPS unitsMeant tocover cleanshutdowns3CachebatteryHolds cacheuntil itflushes4DR sitelinkFail over tothe disastersite5TapebackupLast resortrestore6TherebuildConsultantrebuilt themappingtable byhandTransferswitchfailed,generatorneverstartedThree units,not four, onthe storagecabinetCoin batterydied,mappingtable lostT3 line hadbeen downfor two daysBackup justbefore thecrash haderroredAbout eight hours down end to end.
Six safety nets that failed in one morningA power outage near the data center removed one safety net after another: the generator, the UPS coverage, the cache battery, the link to the disaster recovery site, and the tape backup. The company came back only when a consultant rebuilt the disk mapping table by hand from memory.How the safety nets failed, inorderSix layers built so no single failure couldhurt us1Power, then generatorArea power failedTransfer switch failed, generatornever started2UPS unitsMeant to cover clean shutdownsThree units, not four, on thestorage cabinet3Cache batteryHolds cache until it flushesCoin battery died, mapping tablelost4DR site linkFail over to the disaster siteT3 line had been down for two days5Tape backupLast resort restoreBackup just before the crash haderrored6The rebuildConsultant rebuilt the mapping tableby handAbout eight hours down end to end.

Each layer failed silently in advance, and the outage exposed it.

The power had failed in the area around the data center.

That shouldn’t have mattered: we had a generator. The generator hadn’t come on, because the transfer switch, the device whose one job is to move the building onto generator power, had failed. That shouldn’t have mattered either: the equipment was on UPS units. That would carry the load long enough for clean shutdowns.

There were three UPS units. We needed four.

The cabinet holding roughly five hundred disk drives, the storage heart of the operation, was supposed to be cross-plugged across redundant UPS units. Years earlier I’d given the standing order: dual redundancy on everything, two power paths, two of every path that mattered. The installers hadn’t done it for that cabinet, there was no fourth unit, the cross-plugging went to units already loaded, and nobody had told me. The cabinet lost power without protection.

Still survivable, in theory. When power returned, the cabinet should have restarted. Except one component the size of a quarter had failed too. The little coin battery whose only job is holding the cabinet’s cache alive for the few seconds it takes to flush to disk. The cache died unflushed, and it took with it the master mapping table, the structure that described how five hundred physical drives assembled into the mirrored volumes the business ran on. The drives were fine. The knowledge of what they were was gone.

“Fail over to the DR site,” I said. The T3 line to the disaster recovery site, forty miles away, had gone down two days earlier, and the phone company hadn’t yet come out to repair it. “Then we restore from tape.” The tape backup from just before the crash had errored out. There was no tape.

A server rack holding rack servers, network storage appliances and several tape drives with tape cartridges

A server rack with its tape drives. A tape backup proves itself only at restore time. Copyright © Richard Lowe.

Power, generator, UPS, cache battery, DR link, backup. Six layers, engineered so that no single failure could hurt us, and every one of them had failed. We’d spent years building that protection, and on the one day it mattered, none of it was there.

How was the system rebuilt from memory?

A tape backup proves itself only at restore time.

By then I was at the fair, and I made the call every leader of a remote crisis has to make: a hundred and thirteen miles away, I was more useful on the phone than on the road. We were dead in the water either way. Hours of attempts went nowhere, and then my consultant called with the strangest request of my career: permission to try something he refused to describe.

“I’m not going to tell you. Just give me permission to do it.” We had nothing left to lose, and I said so, and I said do it.

A couple of hours later he called back: he’d rebuilt the disk mapping table by hand. From memory. The table that described how five hundred drives fit together, reconstructed keystroke by keystroke by a man who had internalized the configuration deeply enough to recreate it without documentation. We were down roughly eight hours end to end, and the remainder of the recovery was me walking teams through restarting applications nobody had designed to survive a crash. That’s its own quiet indictment, told in a companion article.

My take

Verify your redundancy with your own eyes. We had six safety nets, power, generator, UPS, cache battery, DR link and tape, and every one failed the same morning. I’d ordered full redundancy years earlier, and nobody told me one cabinet never got it. A standing order means nothing until somebody checks it. Walk the cabinets, test the restores, and chase the dead link the day it drops. A consultant rebuilding a mapping table from memory is a miracle, and you can’t plan on miracles.

Power, generator, UPS, cache battery, DR link, tape backup. Six safety nets engineered so no single failure could hurt us. All six failed in one morning.
Share on X

What failed in the cascading disaster?

The cascade was one management failure wearing six costumes, and I include myself in that. Presumably nobody had ever tested the transfer switch under real failure. The missing fourth UPS was an instruction given and never verified. The coin battery was a consumable nobody was replacing on schedule. The T3 had been down for two days, so the DR site had been fiction for two days and no alarm treated that as an emergency.

We discovered the tape failure at restore time. That means nobody was ever testing restores. Every layer had failed silently, in advance, and the power outage merely conducted the audit.

So the lesson I took wasn’t “have more redundancy,” although we did that too, gutting and rebuilding the entire computer room afterward with redundant everything.

The lesson was check and verify. An instruction isn’t a control. “I ordered dual redundancy” and “we have dual redundancy” are different sentences, and the distance between them was eight hours of downtime and one irreplaceable consultant’s memory. After that, I verified, personally and on a schedule, that what I had ordered existed, and we never had that class of problem again.

Why each safety net failed and what to verify
Safety net Underlying failure What to verify
Generator transfer switch Never tested under real failure Test transfer switches and failover under real conditions
UPS coverage Fourth unit ordered, never installed, nobody checked Walk the cabinets and confirm what was ordered exists
Cache coin battery A consumable nobody replaced on schedule Replace consumable components on schedule
T3 link to DR site Down two days with no alarm treating it as urgent Treat a down DR link as an emergency the day it drops
Tape backup Errored out; restores were never tested Regularly prove that backups restore

Every executive who believes their infrastructure is redundant should take this story into the next operations review and ask one question: when did we last prove it, layer by layer, under failure? Reading the paperwork doesn’t count. An executive who calls redundancy a solved problem because a purchase order says so is being reckless, because the people who pay for that belief are the operations staff working the phones and the business sitting dead in the water while they do.

The same lesson played out on a much bigger stage in October 2026. After Ukrainian drones hit three of Yandex’s five data centers, Geopolitical Futures reported that the company’s thin backup systems delayed the recovery of its financial operations. Its two surviving data centers were left carrying the entire load. The government had been urging big Russian tech companies to improve fault tolerance for over a year. A recovery plan only counts if it survives the disaster it was written for.

For more from this series, see The Disaster Recovery Hub: real disasters, real recoveries, and the plans that survive contact with reality.

Frequently Asked Questions

What is a cascading failure in IT?
A cascading failure happens when one problem knocks out a system’s safety layers one after another until nothing is left standing. I lived through exactly this when a power outage in my data center’s area triggered a failed transfer switch. That meant the generator never kicked in. From there we lost UPS coverage on one cabinet, then a coin-sized cache battery died and erased the disk mapping table, then we found the DR site link had been down for two days, and finally the tape backup errored out. Six separate safety nets, each meant to catch us if another failed, all failed in the same morning. That’s what a cascading failure looks like from the inside.
Why do redundant systems still fail?
Redundant systems fail because redundancy on paper isn’t the same as redundancy in practice. I once gave a standing order for dual power paths on every cabinet, and years later discovered that one cabinet never got the fourth UPS unit I’d ordered, because nobody verified the installation. A coin battery meant to hold cache data alive during a power loss died without anyone noticing it needed replacing. Our disaster recovery link had been down for two days before the crash, and no alarm treated that as urgent. Backups failed too, because nobody had tested a restore until the day we desperately needed one. Every layer had already failed, unnoticed, before the outage exposed it.
How do you prevent cascading infrastructure failures?
Verify instead of instruct: test transfer switches and failover under real conditions, replace consumable components on schedule, treat a down DR link as an emergency, and regularly prove that backups restore.

About the Author
Richard Lowe, professional ghostwriter

Richard Lowe is a professional ghostwriter and author with 113+ books authored and 54+ ghostwritten. Before writing full time he spent 33 years in enterprise technology, including 20 years as Director of Computer Operations and Technical Services at Trader Joe's. He writes nonfiction, fiction and memoir, and works with executives and experts on books that build authority.

More about Richard Lowe →

Disclaimer

The views and opinions expressed in this blog post are solely those of Richard Lowe and are based on personal experience and research. This content is for informational purposes only and should not be construed as professional legal, financial, accounting, or business advice. Always consult with qualified professionals before making important business or legal decisions. Richard Lowe is not a lawyer, accountant, or licensed professional advisor, and this content does not establish any professional relationship.